

As enterprise AI adoption moves past the experimentation stage into production services, finance departments and platform organizations are now facing a shared question together. Can you explain how much you are spending on AI, and which teams and services that spending comes from?
In traditional cloud cost management, instances and storage were the billing units. In AI workloads, the billing unit shifts to tokens. Even the same API call can vary in cost depending on prompt length, response length, and the model selected. When AI agents and MCP servers are added on top of this, automated calls that are not directly triggered by humans occur repeatedly, making cost prediction even harder.
This article organizes the reasons why AI cost control is difficult into three points, and explains what control mechanisms Kong's AI gateway product, Kong AI Gateway, provides at each point.
☑️ What Is AI FinOps
AI FinOps is an operational system that observes LLM tokens, AI agent calls, and related API consumption in real time, and controls consumption to stay within limits set by the organization. The point that distinguishes it from traditional cloud FinOps is that limits are applied at the moment consumption occurs, rather than costs being aggregated and optimized after the fact.
AI cost governance is divided into two pillars. One is unified visibility, observing consumption across LLMs, MCP, APIs, and event streams from a single point. The other is consumption control, actually enforcing defined limits at runtime. This is because visibility alone cannot undo costs that have already been incurred.
☑️ Three Reasons AI Cost Control Is Difficult
AI costs have already risen to a level that changes enterprise decision-making. According to the 2026 State of AI Cost Governance Report, 62% of surveyed companies said that unexpected AI costs changed a business decision over the past year, and 40% said the matter was escalated to board reporting. 33% implemented emergency spending freezes, and 25% delayed or canceled AI initiatives. The cause is not the size of the budget, but the fact that the pathways connecting to AI resources are scattered.
The Problem of Invisible Costs
Only 44% of companies include on-premises AI infrastructure in cost reporting, and only 42% include developer AI tools in reporting. Among companies running agentic workloads, 15% cannot attribute agent-related costs to any unit at all. Costs left out of aggregation cannot become the subject of optimization discussions.
When applications connect directly to each LLM provider, consumption data ends up scattered across provider-specific invoices. An AI gateway is a proxy layer through which all LLM requests pass, so regardless of which provider is used, it leaves request-level token data at the same single point.
The Problem of Unpredictable Costs
Only 11% of companies said they could predict AI costs within a 10% margin of error, while 89% said their predictions were off by more than 10%. Prediction accuracy actually declined from 15% the previous year. The larger the prediction error, the harder it becomes to build plans that reflect AI costs in the cost-of-goods-sold structure.
A more reliable approach than refining predictions is to pre-allocate the total amount. When token limits are distributed by team and by service at the gateway, actual consumption is determined within that range, turning it from something to predict into something to configure.
The Problem of Being Unable to Cut Off Costs
Even if consumption can be checked on a dashboard, if there is no point at which to block a sudden surge in usage by a specific team or model, the cost is only confirmed after it has already been incurred. When control logic is scattered across application code, it also becomes difficult to apply policy consistently at the organizational level.
The gateway sits at the stage before a request reaches the LLM. If a request that exceeds its limit is rejected at this point, the cost is never incurred.
☑️ Why the AI Gateway Becomes the Cost Control Point
An AI gateway is a proxy layer positioned between applications and LLMs. Kong AI Gateway provides a universal API that unifies multiple AI providers under one standardized interface through its AI Proxy and AI Proxy Advanced plugins.
In this structure, client applications are no longer tied to provider-specific API specifications, credentials are managed centrally, and adding a new model does not require rebuilding integration work for every application.
From a cost perspective, what this structure means is that the control point becomes consolidated into one place. When token limits and usage aggregation that were previously implemented individually per application are moved into gateway configuration, policy can be applied and changed at the organizational level.
☑️ Cost Control Features Provided by Kong AI Gateway
Token- and Cost-Based Rate Limiting
In LLM traffic, rate limiting based on request count is hard to make meaningful. This is because the cost of a single short question and a single request to summarize a long document differ significantly.
The AI Rate Limiting Advanced plugin applies limits based on token data returned by the LLM provider. You can choose from methods that sum prompt and response tokens together, count only input tokens, count only generated tokens, or use an approach based on actual cost that reflects per-model input/output pricing.
The reason the cost-based approach is meaningful from a financial standpoint is that the same number of tokens can cost different amounts depending on which model was used. Setting limits in cost units makes the budget unit managed by the finance department the same as the limit unit enforced by the gateway.
Limits can be defined per consumer, consumer group, model, and provider, making it possible to configure a separate limit only for cases where a specific team calls a specific model.
Tiered Limit Allocation and Model Access Restriction
Being able to set a limit and deciding how to divide it among people are different problems. Kong AI Gateway supports hierarchical access control that divides consumers into tiers and applies different token limits per tier. For example, you could configure a Gold tier at 1,000 tokens per 30 seconds, a Silver tier at 500 tokens per 30 seconds, and a Bronze tier at 100 tokens per minute.
Model access restrictions can be applied alongside this. By blocking lower-tier consumers from accessing higher-tier models, you can keep higher-priced models open only for the work that actually needs them. If a request exceeds its limit or calls a model it isn't permitted to use, the gateway returns a 429 response.
In customer environments, this configuration connects directly to budget allocation by team. When policy at the gateway defines which organization can use which model and how much, the path from a usage spike to a budget overrun is cut off.
Semantic Caching and Model Routing
Means of reducing consumption itself can also be applied at the gateway layer.
With semantic caching, the gateway directly returns a response for prompts with similar meaning. In scenarios like internal assistants or customer support where the same question repeats in different wording, no LLM call occurs at all, reducing token consumption.
Semantic routing distributes requests to different models based on the meaning of the prompt. Instead of sending every request to a top-tier model, it selects a model appropriate to the difficulty of the task. Routing criteria can include cost, prompt semantics, and latency.
From an operational standpoint, what matters is that model selection criteria are managed through gateway configuration rather than code. When a new model is released or pricing changes, routing policy can be adjusted without an application deployment.
Controlling MCP and Agent Traffic Costs
MCP adoption tends to increase the volume of LLM calls. This is because an MCP client connects to an MCP server, the server in turn calls the LLM, and token consumption occurs at each of these touchpoints.
Kong AI Gateway controls MCP traffic at the gateway and provides features that reduce token spend through MCP context optimization. It also collects per-call latency, token usage, and error information for agent-to-agent communication.
In agent workflows, prior conversation history and tool call results keep accumulating in the prompt, so input tokens can account for a substantial share of total cost. Cleaning up context at the gateway layer can reduce consumption without modifying application logic.
Token Usage Data and Quota Management
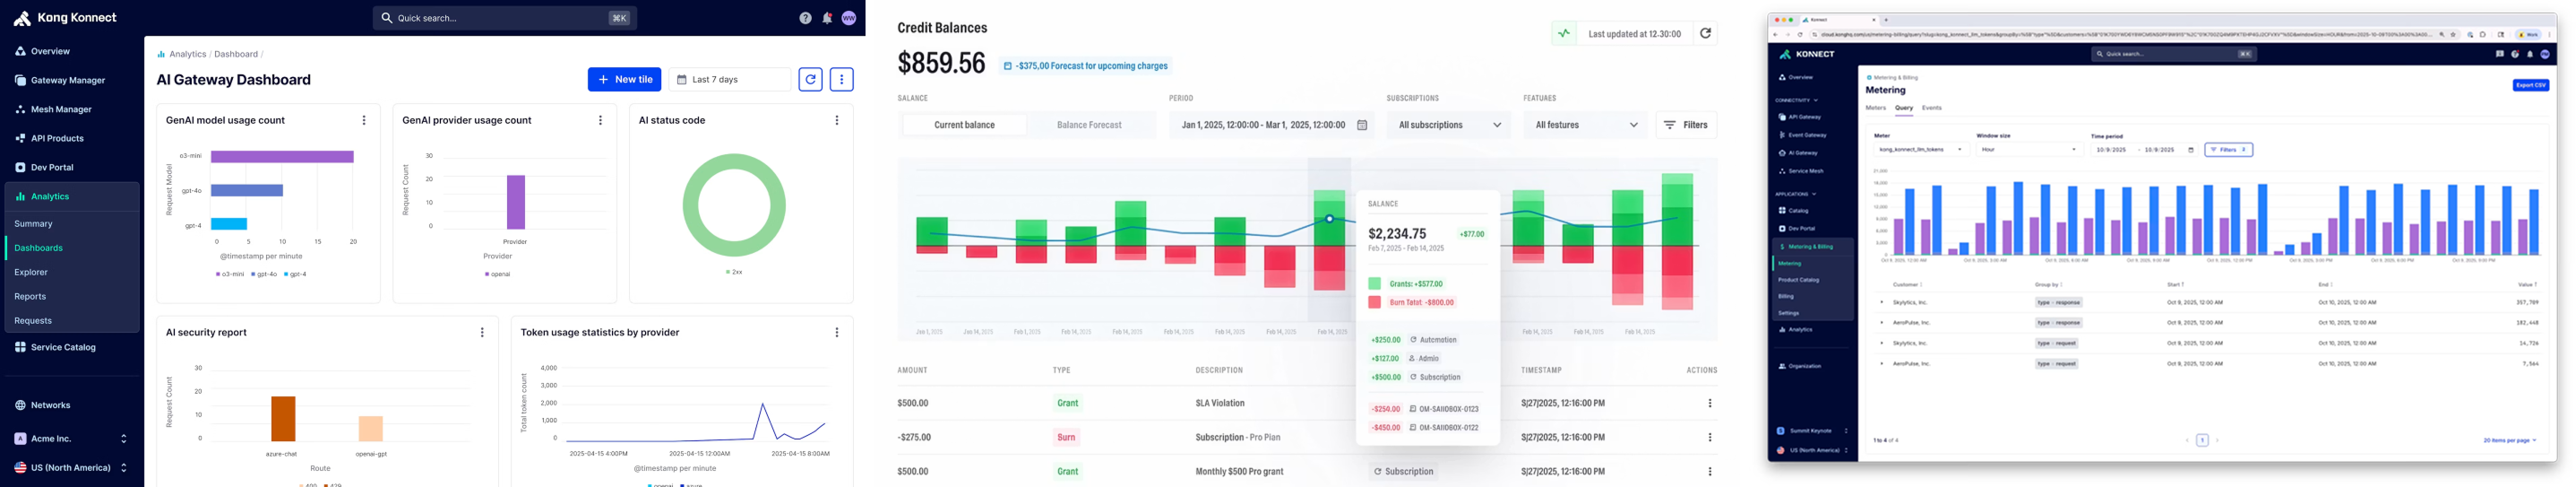
Kong AI Gateway tracks token usage, latency, and cost through audit logs, LLM metrics, and OpenTelemetry-based tracing. This data can be exported to an observability stack already in operation, so there's no need to build a separate analytics environment from scratch.
What cost reporting needs is not a total figure but broken-down data. Usage must be distinguishable by which consumer called which model and how much, in order to build per-team usage reports.
Quotas based on user, model, and time period can also be set alongside this. If rate limiting is a means of preventing spikes within a short time window, quotas are a means of managing total volume over a longer period, such monthly.
☑️ Frequently Asked Questions
How is AI FinOps different from traditional cloud FinOps?
The billing unit and the point of control are different. Traditional cloud FinOps centers on aggregating instance and storage usage after the fact for optimization, whereas AI FinOps deals with the variable unit of tokens and requires runtime control that enforces limits at the moment of consumption.
Why should limits be based on tokens rather than request count?
Because per-request cost variance in LLM requests is large. If a short question and a long document summary are counted as the same single request, actual spend and the limit fall out of alignment. Limits need to be set on a token basis — particularly a cost basis that reflects per-model pricing — for the budget unit and the control unit to match.
Can't token limits be implemented in application code without an AI gateway?
It's possible, but it requires individual implementation in every application, and there is no single point at which total organization-wide consumption can be aggregated and judged. Placing control at the gateway layer allows the same policy to be applied across multiple applications and agents, and policy changes do not require an application deployment.
Can different limits be applied per team?
Yes. Consumers can be divided into tiers with different token limits set per tier, and it is also possible to restrict which models are accessible based on tier. This allows budget to be allocated by keeping higher-priced models open only to the organizations that need them.
Can this be applied in environments using multiple LLM providers together?
Yes. Through the universal API provided by AI Proxy and AI Proxy Advanced, multiple providers can be unified under a single interface, with separate limits set at the provider and model level. Even in environments that combine on-premises models with commercial LLMs, consumption can be checked from the same single point.
☑️ Closing
The AI cost problem is less about reducing usage and more about creating a point where usage can be seen and cut off. The gateway layer through which LLM traffic passes is the location where token data can actually be verified, and it is where visibility and limit enforcement can both be handled at the same point.
CloudNetworks, as a Kong partner, supports the building of AI gateways. By reviewing your current LLM traffic structure, the model configuration in use, and your requirements for distinguishing usage by team together, we can determine which control policy would be appropriate to apply first. If you are considering AI cost visibility and token usage control, please feel free to contact us.
▶ Learn more about Kong AI Gateway
[Source: Kong, "AI Cost Governance Solution for FinOps," https://konghq.com/solutions/ai-cost-governance-finops, Mavvrik, Benchmarkit, "2026 State of AI Cost Governance Report," https://www.mavvrik.ai/state-of-ai-cost-governance-report/, Kong, "AI Cost Optimization Solutions," https://konghq.com/solutions/ai-cost-optimization-management, Kong, "Streamline AI Usage with Token Rate-Limiting & Tiered Access in Kong," https://konghq.com/blog/engineering/token-rate-limiting-and-tiered-access-for-ai-usage, Kong, "Secure, Scalable AI Gateway for AI Connectivity," https://konghq.com/products/kong-ai-gateway, Kong Docs, "AI Rate Limiting Advanced," https://developer.konghq.com/plugins/ai-rate-limiting-advanced/]