

For organizations running Kubernetes clusters, cloud costs rising faster than expected usually comes down to the compute layer. Nodes stay up that are larger than what workloads actually consume, and those nodes remain in place even after traffic drops off. Traditional node-group-based autoscaling struggles to fully solve this problem. Because instance types and group sizes are predefined and scaling only happens within that predefined range, a gap remains between actual scheduling demand and node specifications.
Karpenter is an open source project built to close that gap at the node layer. That said, not all of the remaining gap sits at the node layer alone. This post walks through how Karpenter works and how consolidation functions, then looks at how Cast AI's Karpenter Enterprise Suite addresses what's left outside the node layer.
☑️ What Is Karpenter
Karpenter is an open source Kubernetes node autoscaler that watches for unschedulable pods and provisions right-sized nodes directly through cloud provider APIs at the moment they're needed. Instead of scaling a predefined node group, it selects the best-fit, lowest-cost instance for each scheduling event. When demand drops, it consolidates workloads onto fewer nodes to reduce idle compute cost.
AWS developed Karpenter and open sourced it in 2021. The project reached beta in 2023, and AWS contributed the vendor-neutral core to the CNCF through the Kubernetes Autoscaling Special Interest Group. v1.0 launched in 2024, and as of this writing the latest version is v1.14.
Karpenter sits alongside the Horizontal Pod Autoscaler (HPA) and Vertical Pod Autoscaler (VPA) as part of the Kubernetes autoscaling ecosystem, but its scope is the node layer — how many machines are running, what specs they have, and how quickly they're terminated once demand drops.
☑️ How Karpenter Provisions Nodes
Watching for unschedulable pods
Through its controller, Karpenter watches the Kubernetes API for pods in an Unschedulable state. When none of the existing nodes can accommodate a pod, the scheduler marks it as pending, and at that point Karpenter evaluates the pod's resource requests, node selectors, tolerations, and affinity rules. It then selects the smallest, cheapest instance type among those that satisfy all constraints and provisions it. What this means in practice is that the decision on node specs happens later, at the point of actual demand — operators no longer need to forecast and predefine instance types in advance; the node is determined by the conditions present at the moment scheduling is actually required.
The range of instance types Karpenter considers
Where Karpenter differs most from traditional autoscalers is the breadth of instance selection. It evaluates hundreds of instance types simultaneously, across families and sizes. For example, if a pod requires 4 vCPU and 8 GiB of memory, Karpenter reviews every instance type that meets those requirements, ranks them by current cost, and provisions the best fit. Spot availability, region-specific pricing, and the capacity-type preferences defined in the NodePool all factor into this decision. The expected benefit is better bin-packing quality from the very start of provisioning, since nodes are built around the workload rather than workloads being fit into predefined node shapes.
Just-in-time provisioning vs. node groups
Traditional node-group autoscaling requires instance types and group sizes to be defined in advance, and the autoscaler scales those groups up or down as a unit. This often leaves nodes that are far larger than what's actually running on them. Karpenter has no concept of a node group. It creates the node it needs, just in time, for each scheduling event, and deprovisions it once the workload no longer needs it. Shorter node lifecycles translate directly into lower idle compute cost.
☑️ Consolidation and Bin-Packing
How nodes are removed and workloads rescheduled
Consolidation is the mechanism Karpenter uses to reclaim idle compute. It runs continuously, checking whether nodes are empty or underutilized. Once it identifies a target node, it evicts the pods on that node, terminates the node, and reschedules the workloads onto the remaining nodes.
Which nodes are considered targets is determined by the consolidationPolicy value, and there are three options. If left unset, consolidationPolicy defaults to WhenEmptyOrUnderutilized and consolidateAfter defaults to 0s.
WhenEmpty targets only nodes that are empty — meaning only pods with no disruption cost, such as DaemonSets, remain on them. This is the most conservative of the three policies.
WhenEmptyOrUnderutilized targets any node that can be removed or replaced to reduce cost. It delivers the largest savings, but also comes with the most pod disruption.
Balanced scores savings against pod disruption together, and only runs consolidation when the savings are meaningfully larger than the disruption involved. Nodes that are empty or clearly underutilized still get cleaned up, but marginal actions with small savings are skipped. This is a good fit for clusters with frequent workload churn, where constant node replacement would be too disruptive.
According to Cast AI's 2026 State of Kubernetes Optimization Report, average CPU utilization across Kubernetes clusters sits at 8%, with cluster-wide CPU overprovisioning around 69%. Karpenter's just-in-time provisioning and consolidation directly address the portion of that waste that lives at the node layer. However, low utilization also reflects overrequested pod resources, which Karpenter alone doesn't resolve.
Disruption controls
Because consolidation is powerful, excessive eviction can affect running workloads. Karpenter provides two control mechanisms. consolidateAfter is the amount of time a node waits for new work before becoming a consolidation candidate — the timer resets every time a pod is added to or removed from the node, so a node has to stay stable for that duration before it's eligible. Setting this value higher gives volatile workloads room to settle and reduces how often consolidation runs. Setting it to Never disables consolidation for that NodePool entirely.
The second control is the disruption budget. The budgets array allows fine-grained control over the pace of disruption.
| disruption: budgets: - nodes: "10%" - nodes: "5" schedule: "@daily" duration: 1h |
The first entry caps concurrent disruption at 10% of total nodes. The second entry is a budget scoped to a cron schedule and duration, adding an additional cap of 5 nodes during that window. When multiple budgets apply, Karpenter uses the most restrictive one. If no budget is defined, nodes: 10% is applied by default.
Pod-level controls also apply. Pods covered by a blocking PodDisruptionBudget (PDB) won't be evicted, and any node hosting such a pod is excluded from voluntary disruption. If pods on a single node belong to different PDBs, all of them have to permit eviction at the same time, so the more PDBs attached to a node, the fewer consolidation opportunities remain. In environments with little tolerance for service interruption — finance, manufacturing, public sector — how these settings are configured becomes a central point of evaluation before adoption.
☑️ Core Components of Karpenter
NodePool and NodeClass
Karpenter relies on two core CRDs. NodePool defines scheduling constraints such as architecture, capacity type, and instance family, along with resource limits and disruption policy. NodeClass defines cloud-provider-specific infrastructure settings — on AWS, EC2NodeClass specifies AMI selection, subnets, security groups, and IAM roles. This separation is intentional: the platform team owns the NodeClass, which maps to cloud configuration, while individual teams define NodePool constraints suited to their own workloads. Infrastructure policy stays centrally managed, while workload scheduling policy can be handled flexibly at the team level.
The following NodePool example allows both on-demand and spot capacity on amd64 instances, sets a cluster-wide CPU limit of 1,000, and enables WhenEmptyOrUnderutilized consolidation with a 10% node disruption budget.
| apiVersion: karpenter.sh/v1 kind: NodePool metadata: name: default spec: template: spec: requirements: - key: kubernetes.io/arch operator: In values: ["amd64"] - key: karpenter.sh/capacity-type operator: In values: ["on-demand", "spot"] nodeClassRef: group: karpenter.k8s.aws kind: EC2NodeClass name: default limits: cpu: "1000" disruption: consolidationPolicy: WhenEmptyOrUnderutilized budgets: - nodes: "10%" |
Its paired EC2NodeClass specifies the AMI alias, IAM role, and subnet and security group selectors.
| apiVersion: karpenter.k8s.aws/v1 kind: EC2NodeClass metadata: name: default spec: amiSelectorTerms: - alias: al2023@latest role: "KarpenterNodeRole-my-cluster" subnetSelectorTerms: - tags: karpenter.sh/discovery: "my-cluster" securityGroupSelectorTerms: - tags: karpenter.sh/discovery: "my-cluster" |
What happens when drift occurs
Drift refers to a state where a node's running configuration no longer matches the NodePool spec. When a new AMI version becomes available or requirements change, Karpenter marks the affected node as drifted and replaces it automatically. This keeps declared configuration and actual node state in sync without manual rollouts or blue-green node group management.
☑️ Karpenter vs. Cluster Autoscaler
The key difference between the two comes down to scope. Cluster Autoscaler scales predefined node groups with fixed instance types. Karpenter, by contrast, provisions individual nodes directly through the cloud API, choosing from every available instance type. Operationally, Cluster Autoscaler only operates within pre-configured group boundaries, while Karpenter responds to scheduling events by selecting the optimal instance type in the moment. Deprovisioning works the same way: Karpenter handles it itself through consolidation logic, while Cluster Autoscaler relies on group-level scale-down heuristics.
That said, Cluster Autoscaler is more mature outside of AWS, and in some environments has broader community support. The right choice depends on which cloud provider is in use and how much appetite there is for manually maintaining node group templates.
☑️ Karpenter Support by Cloud Provider
Karpenter has the broadest support on AWS. EKS Auto Mode was announced at AWS re:Invent 2024 and reached general availability in December 2024, letting new EKS clusters enable Karpenter without a separate Helm install or controller deployment.
Azure AKS launched general availability for Karpenter-based node provisioning via Node Auto Provisioning in the second half of 2024. The Azure provider supports most common workload patterns and uses the same NodePool CRD structure as the AWS provider.
GCP and GKE are a different story. As of this writing, there's no official Karpenter provider for GKE. A community-maintained option exists, but it isn't production-supported and doesn't yet have feature parity with the AWS and Azure providers. Organizations running on GCP should evaluate other node autoscaling approaches alongside Karpenter before committing.
☑️ What Karpenter Doesn't Solve on Its Own
This is the part referenced in the intro — what's left outside the node layer. Karpenter is effective at node provisioning and consolidation, but there are three areas it can't address on its own.
The most common gap is overrequested pods. If a container requests 4 CPU but actually uses 0.3, Karpenter still provisions a node sized to accommodate the full request. The gap between what a pod asks for and what it actually consumes isn't a node provisioning problem — it's a pod resource request problem.
Stateful workloads face a different constraint. When Karpenter consolidates, it evicts pods. That's not an issue for stateless workloads that can tolerate disruption, but for stateful workloads relying on persistent connections or local storage, eviction can translate directly into downtime.
The third is spot instance risk. Karpenter handles interruption signals reactively, after the fact, and doesn't have ML-based capability to predict which spot instances a cloud provider is likely to reclaim.
☑️ Where Cast AI's Karpenter Enterprise Suite Fills the Gap
Karpenter Enterprise Suite is a commercial product Cast AI launched in May 2026, built for AWS-based Kubernetes clusters, where Karpenter adoption is most active.
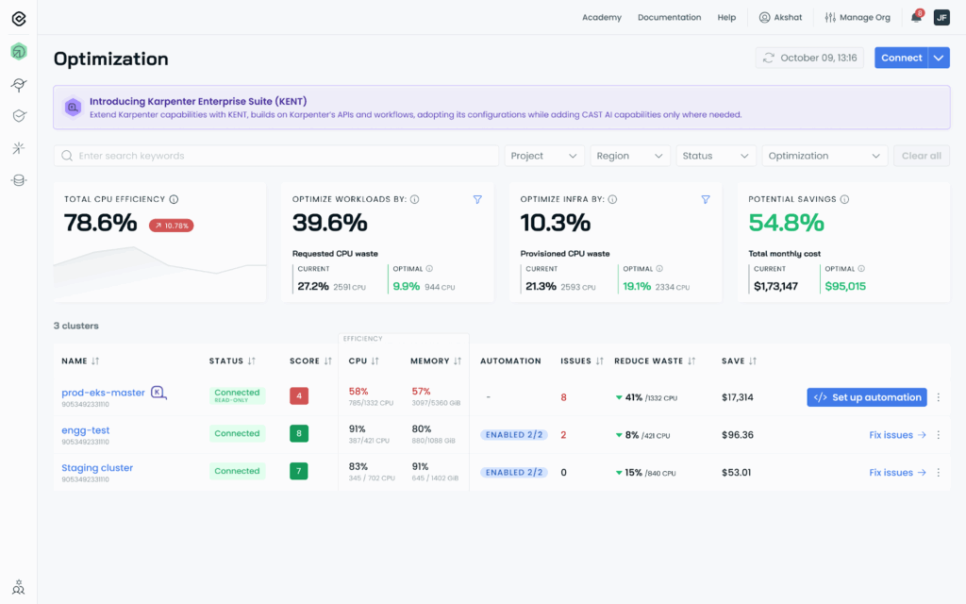
The premise of the product is that it doesn't replace Karpenter. Karpenter continues to serve as the autoscaler, executing node lifecycle actions, while Cast AI adds a layer of analysis, optimization, and automation on top. The existing NodePool and EC2NodeClass configurations remain the source of truth; once optimization features are enabled, Cast AI reads and modifies those CRDs to inform its provisioning decisions. Onboarding starts with a script that deploys a lightweight agent on top of the existing Karpenter setup — there's no need to reconfigure an existing Karpenter environment, which makes this relevant both for organizations already running Karpenter and those just adopting it. Once a cluster is connected, Cast AI automatically detects that Karpenter is running and evaluates workload usage, node selection, spot behavior, and overall cluster efficiency.
The level of automation is up to the organization. It can be used purely to surface optimization opportunities, or configured to automatically execute rightsizing, consolidation, rebalancing, and spot handling. Organizations can first see the scale of potential savings, then turn on features incrementally as they're ready. These decisions are driven by machine learning models trained on workload behavior, resource usage, and spot market conditions collected across tens of thousands of connected clusters — used to forecast resource demand, identify stable spot pools, and detect the likelihood that a node will be interrupted.
Workload rightsizing
Karpenter scales nodes based on pod resource requests, but those requests are often set well above or below actual workload needs. Cast AI measures actual CPU and memory usage over time and adjusts requests accordingly. In practice, this extends the scope of optimization from the node down to the pod: as pods request only what they actually need, the node specs Karpenter provisions shrink accordingly. The goal is reducing waste without repeated manual tuning, while keeping workload stability intact.
Container live migration
Most autoscalers rely on eviction when rebalancing nodes, which can affect stateful services, streaming applications, and large JVM workloads. Cast AI's container live migration moves running workloads to new nodes without restarting them. Because it works with persistent storage, workloads that were previously difficult to move become eligible for migration too, and reduced node fragmentation opens up more room for bin-packing.
This feature is applied selectively, to supported workloads. Other optimization features like rightsizing and spot management still work without it. The practical difference is that in environments with little tolerance for disruption, workloads where eviction would have meant downtime can now be included in consolidation.
Spot interruption prediction and capacity management
Spot instances offer significant cost savings, but unpredictable interruptions can affect workloads. Cast AI analyzes spot behavior to forecast the likelihood of interruption and evaluates relatively stable spot pools. When spot capacity isn't available, it shifts workloads to on-demand and reverts once spot capacity is available again. Operationally, this raises spot adoption while reducing the time teams spend responding to interruptions.
Continuous rebalancing and placement optimization
Karpenter provisions nodes efficiently, but cluster usage patterns keep shifting throughout the day. Cast AI's rebalancer analyzes how workloads are distributed across all nodes, consolidates underutilized nodes, and improves overall distribution through its placement logic — which also factors in disruption budgets and workload constraints. It also automatically hibernates dev and staging clusters to eliminate idle spend.
Cost visibility and allocation
Cast AI provides detailed visibility into resource usage and the associated costs. Savings from rightsizing, spot usage, and consolidation are visible, and costs can be viewed by workload, namespace, or team. This is an area Karpenter alone doesn't address. When engineering and FinOps teams look at cost through different lenses, having a shared dataset for team-level chargeback is a practical difference.
In summary, Karpenter handles the node layer, and Cast AI handles the workload layer on top of it. Cast AI states that customers combining Karpenter with its rightsizing and spot management typically see cloud cost savings in the 30–70% range.
☑️ Frequently Asked Questions
What is Karpenter?
Karpenter is an open source Kubernetes node autoscaler that provisions right-sized compute nodes on demand, without predefined node groups. It watches for unschedulable pods, selects the optimal instance type, and calls the cloud API directly to create nodes. AWS developed it in 2021 and contributed it to the CNCF through the Kubernetes Autoscaling SIG in 2023; v1.0 launched in 2024.
How does Karpenter reduce costs?
Through two mechanisms. First, it provisions right-sized nodes at creation time, avoiding waste from oversized instances. Second, it continuously consolidates by removing empty or underutilized nodes and rescheduling workloads onto fewer machines. There are three consolidation policies — WhenEmpty, WhenEmptyOrUnderutilized, and Balanced — with WhenEmptyOrUnderutilized applied by default if none is set.
Is Karpenter available only on AWS?
No. Azure AKS has supported it in general availability via Node Auto Provisioning since the second half of 2024. GKE, however, has no official provider as of this writing; a community-maintained provider exists but lacks production support and feature parity with the AWS and Azure providers.
Should I choose Karpenter or Cluster Autoscaler?
Cluster Autoscaler scales predefined node groups with fixed instance types, while Karpenter provisions individual nodes directly through the cloud API and can choose from any instance type. Karpenter tends to win on bin-packing quality and provisioning speed, but it depends on the cloud provider having a supported Karpenter node provider.
What is Karpenter Enterprise Suite?
Karpenter Enterprise Suite is Cast AI's commercial product that adds workload-level optimization, safe consolidation, spot intelligence, and cost visibility on top of open source Karpenter. Node provisioning stays with Karpenter, while Cast AI adds automation and decision logic to improve efficiency and stability.
Does Cast AI replace Karpenter?
No. Karpenter continues to serve as the node autoscaler; Cast AI works alongside it to strengthen scaling and consolidation decisions, while Karpenter executes the actual node lifecycle actions. Once a cluster is connected, Cast AI automatically detects Karpenter and evaluates workload usage, node selection, spot behavior, and overall cluster efficiency.
What does Cast AI address that Karpenter doesn't?
Karpenter focuses on node provisioning. Cast AI adds usage-based workload rightsizing, safe consolidation via container live migration, predictive spot handling, continuous rebalancing, and cost and efficiency visibility by workload and team.
Is container live migration required?
No. It's applied selectively to supported workloads and helps reduce the disruption impact of consolidation and rebalancing. Other Cast AI optimization features work fine without it.
Does Cast AI take action automatically, or just suggest?
Both are possible. It can be used purely to surface optimization opportunities, or configured to automatically run rightsizing, consolidation, rebalancing, and spot handling. How much automation to apply is up to the operating organization.
Who is Karpenter Enterprise Suite for?
Both organizations already running Karpenter and those evaluating or just starting to adopt it. Onboarding is a script that deploys a lightweight agent on top of the existing Karpenter setup, with no need to reconfigure the existing environment. The target environment is AWS-based Kubernetes clusters, where Karpenter adoption is most active.
☑️ Closing
Karpenter has established itself as a way to reduce waste at the node layer of Kubernetes cost structure. Selecting instances per scheduling event and continuously reclaiming underutilized nodes narrows the gap left by node-group-based autoscaling. That said, challenges outside the node layer — overrequested pod resources, stateful workload eviction, spot interruption prediction — require a separate optimization layer on top of Karpenter.
CloudNetworks supports the adoption of cost optimization for Karpenter environments, built on Cast AI. If you're already running Karpenter, you can apply Karpenter Enterprise Suite while keeping your existing NodePool and EC2NodeClass configuration intact, extending optimization to workload rightsizing, spot stability, and team-level cost visibility. If you'd like to check your current cluster's utilization and potential savings, please reach out to CloudNetworks.
▶ Learn more about Cast AI
[Sources: CAST AI, "What Is Karpenter? How Just-in-Time Node Provisioning Cuts Kubernetes Cost," https://cast.ai/blog/what-is-karpenter/; CAST AI, "Karpenter Just Got Smarter: Cast AI Brings Enterprise-Grade Optimization to Kubernetes Autoscaling," https://cast.ai/blog/cast-ai-for-karpenter/; CAST AI, "Karpenter Enterprise Suite | Overview," https://docs.cast.ai/docs/karpenter-enterprise; CAST AI, "Karpenter Optimization with Automation Guardrails," https://cast.ai/karpenter-optimization/; Karpenter, "Disruption," https://karpenter.sh/docs/concepts/disruption/; CNCF, "What Karpenter v1.0.0 means for Kubernetes autoscaling," https://www.cncf.io/blog/2024/11/06/karpenter-v1-0-0-beta/]